For a market research analyst at an independent research firm, knowing what's happening across industries requires talking to people — 20–30 stakeholder interviews, focus groups, and expert calls every quarter. For years, those recordings accumulated in a folder until someone needed them and the team had to re-listen. AI transcription changed that — but only once it was clear which tools actually worked and which oversold their accuracy.
AI transcription converts spoken audio to text using machine learning. The technology has improved substantially in the last two years and now reliably handles professional audio quality in most major languages. What distinguishes tools from each other isn't primarily accuracy (the best tools are now competitive) but workflow integration, format support, and what the tool returns beyond the raw text.
How AI Transcription Works
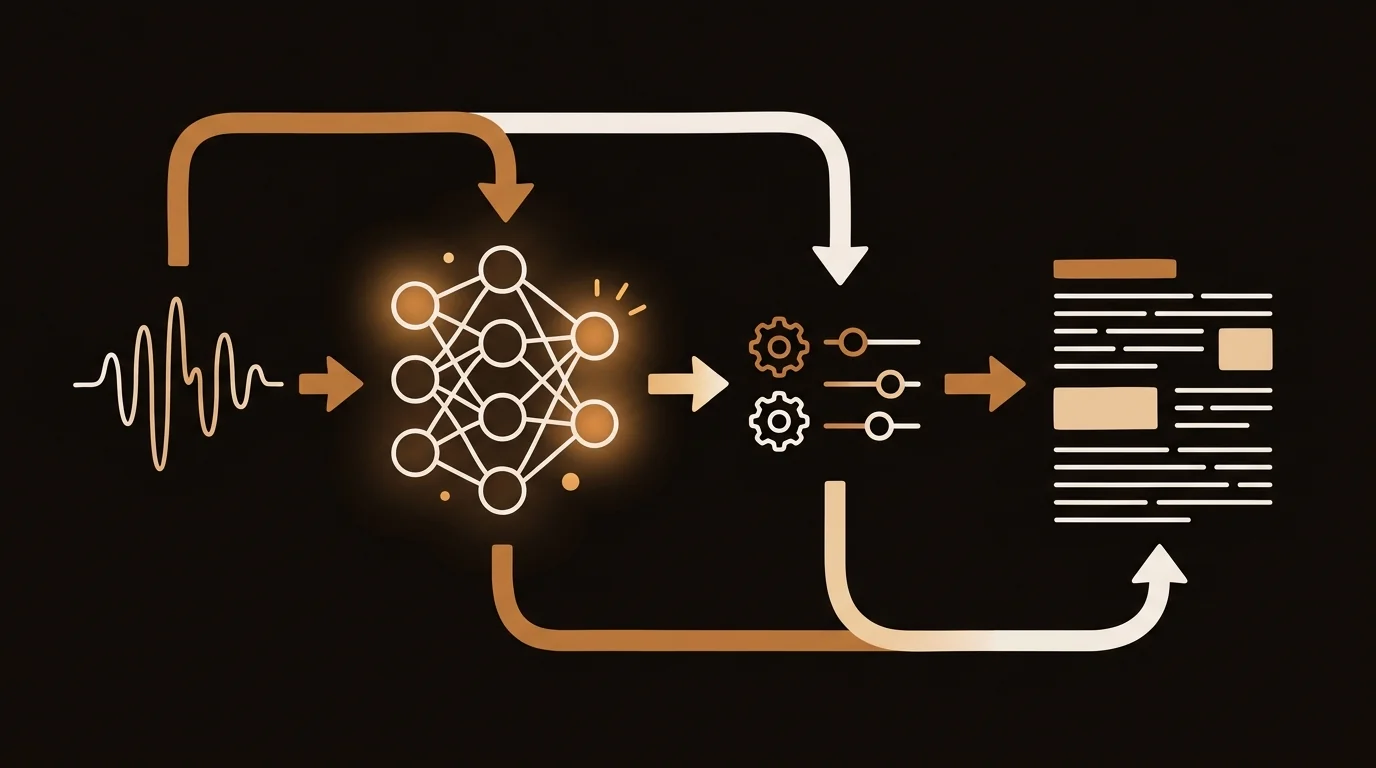
Modern AI transcription uses a two-part process: an acoustic model that identifies phonemes (the basic sound units of speech) in the audio signal, and a language model that assembles those phonemes into likely word sequences based on context.
The acoustic model processes audio features — frequency patterns, timing, speaker characteristics — and outputs phoneme probabilities. The language model then uses these probabilities along with learned patterns of how words follow each other to generate the most probable word sequence. Context matters: "I work in a neural network" produces different output than "I hurt my neural nerves" even if the acoustic signals for "neural" are similar.
State-of-the-art systems like OpenAI's Whisper and Deepgram's nova-3 use transformer architectures that process audio features directly, without separating the acoustic and language modeling steps. This end-to-end approach produces better results on conversational speech than older pipeline-based systems.
Speaker diarization — identifying who said what — is a separate capability layered on top of transcription. It analyzes voice characteristics (pitch, speaking rate, tonal patterns) to segment audio by speaker. Accuracy is highest when speakers have distinct voices and minimal overlap; it degrades when multiple speakers have similar voice characteristics or frequently interrupt each other.
Accuracy: What the Numbers Mean in Practice
Word error rate (WER) is the standard accuracy metric: the percentage of words in the transcript that differ from the actual spoken words. A WER of 8% means roughly 8 words per 100 are incorrect.
For a 30-minute stakeholder interview of approximately 4,500 words:
- 8% WER = approximately 360 errors — still plenty of effort to correct
- But: most errors are on proper nouns, not content words. The meaning is usually clear even with proper noun errors.
For research use — capturing the substance of what was said for analysis — 8–12% WER is workable with a targeted 10-minute review focused on proper nouns and critical data points. For verbatim citation, every word matters, and WER below 5% is the threshold.
Vendor benchmarks, including Deepgram's for nova-3, are measured under laboratory conditions — real-world audio typically produces higher WER due to variable recording quality.
Which AI Transcription Tools Are Worth Using
sipsip.ai — Best for Research + Multi-Format Support
Model: Deepgram nova-3 (existing captions first for YouTube links)
Formats: YouTube URLs, podcast links, MP3/MP4/WAV/M4A uploads
Output: Transcript + AI summary + key points
Free tier: start without an account, and a free sign-in keeps you going
For market research workflows, sipsip.ai's combination of format support and structured output is the most practical. It's the hosted version of AI-Video-Transcriber, an open-source transcriber with more than 3,300 GitHub stars. Any interview recording (MP4 from Zoom, M4A from iPhone Voice Memos, WAV from a dedicated recorder) uploads directly. The AI summary gives a 60-second read on what the interview covered before committing to full review; the key points extract the most important claims for research notes.
The multi-format support is what differentiates it from tools that only handle one input type. In a research workflow, Zoom recordings, podcast interviews on the research topic, and YouTube presentations from industry experts all go through the same tool and the same workflow.
Otter.ai — Best for Live Meeting Transcription
Model: Otter proprietary
Formats: Live meetings, audio uploads
Output: Transcript + meeting summary + action items
Free tier: 300 minutes/month
Otter's strength is live meeting integration — the Otter bot joins Zoom, Teams, or Meet and generates real-time transcription with speaker labels. For organizations whose primary transcription need is live meetings (not external research interviews), Otter's workflow integration is cleaner than uploading recordings after the fact.
The limitation for research use: Otter doesn't handle YouTube or podcast URLs, and its accuracy on audio with heavy accents or technical vocabulary is below Deepgram-based tools in practice.
Riverside — Best Audio Quality + Transcription Combined
Model: Built-in AI transcription
Formats: Live recording + transcription
Output: High-quality audio/video + transcript
Free tier: Limited hours
Riverside is a recording platform first — it captures high-quality remote audio by recording locally on each participant's device before uploading. The transcription is built in. For research interviews where recording quality is important (journalist or qualitative researcher), Riverside's recording quality advantage directly improves transcription accuracy.
The workflow is different from upload-based tools: you record within Riverside, and the transcript is generated from the high-quality local recording rather than a compressed video conference stream.
AssemblyAI — Best for Developers and High Volume
Model: AssemblyAI Universal-2
Formats: API-based, all audio formats
Output: Transcript + speaker labels + topic detection + sentiment
Free tier: API credits available
AssemblyAI is primarily a developer API, not a consumer tool. For organizations building transcription into their workflow via API — integrating automatic transcription into a CRM, a research platform, or a content management system — AssemblyAI's API is well-documented and capable. The Universal-2 model includes topic detection and sentiment analysis alongside the transcript, which is valuable for qualitative research at scale.
For individual use without development resources, AssemblyAI's API-first design makes it less accessible than consumer tools.
When AI Transcription Needs Human Review
AI transcription in 2026 handles most professional audio well. It still requires human review in these cases:
High-stakes verbatim use: legal proceedings, medical documentation, published journalism — any context where every word matters.
Heavy accents on uncommon languages: accuracy on accented speech in lower-resource languages is still inconsistent.
Overlapping speech: multi-speaker recordings with frequent interruptions cause errors that compound.
Highly specialized jargon: domain-specific terminology in niche fields (specific financial instruments, rare medical terminology, specialized engineering terms) has higher error rates.
For qualitative research use — where the goal is understanding themes and arguments, not verbatim documentation — AI transcription accuracy is sufficient for most use cases, with a focused 10-minute review per hour of audio.
The audio transcription guide covers the full accuracy landscape with per-tool benchmarks across different audio quality categories.
Sofia Andersson is a market research analyst at an independent research firm. She runs 20–30 stakeholder interviews per quarter and uses sipsip.ai to transcribe and organize interview recordings for qualitative analysis.
Frequently asked questions
I'm a market research analyst at an independent research firm. I run 20–30 stakeholder interviews per quarter and rely on AI transcription to make those recordings useful.